What Are Brand Name Normalization Rules?
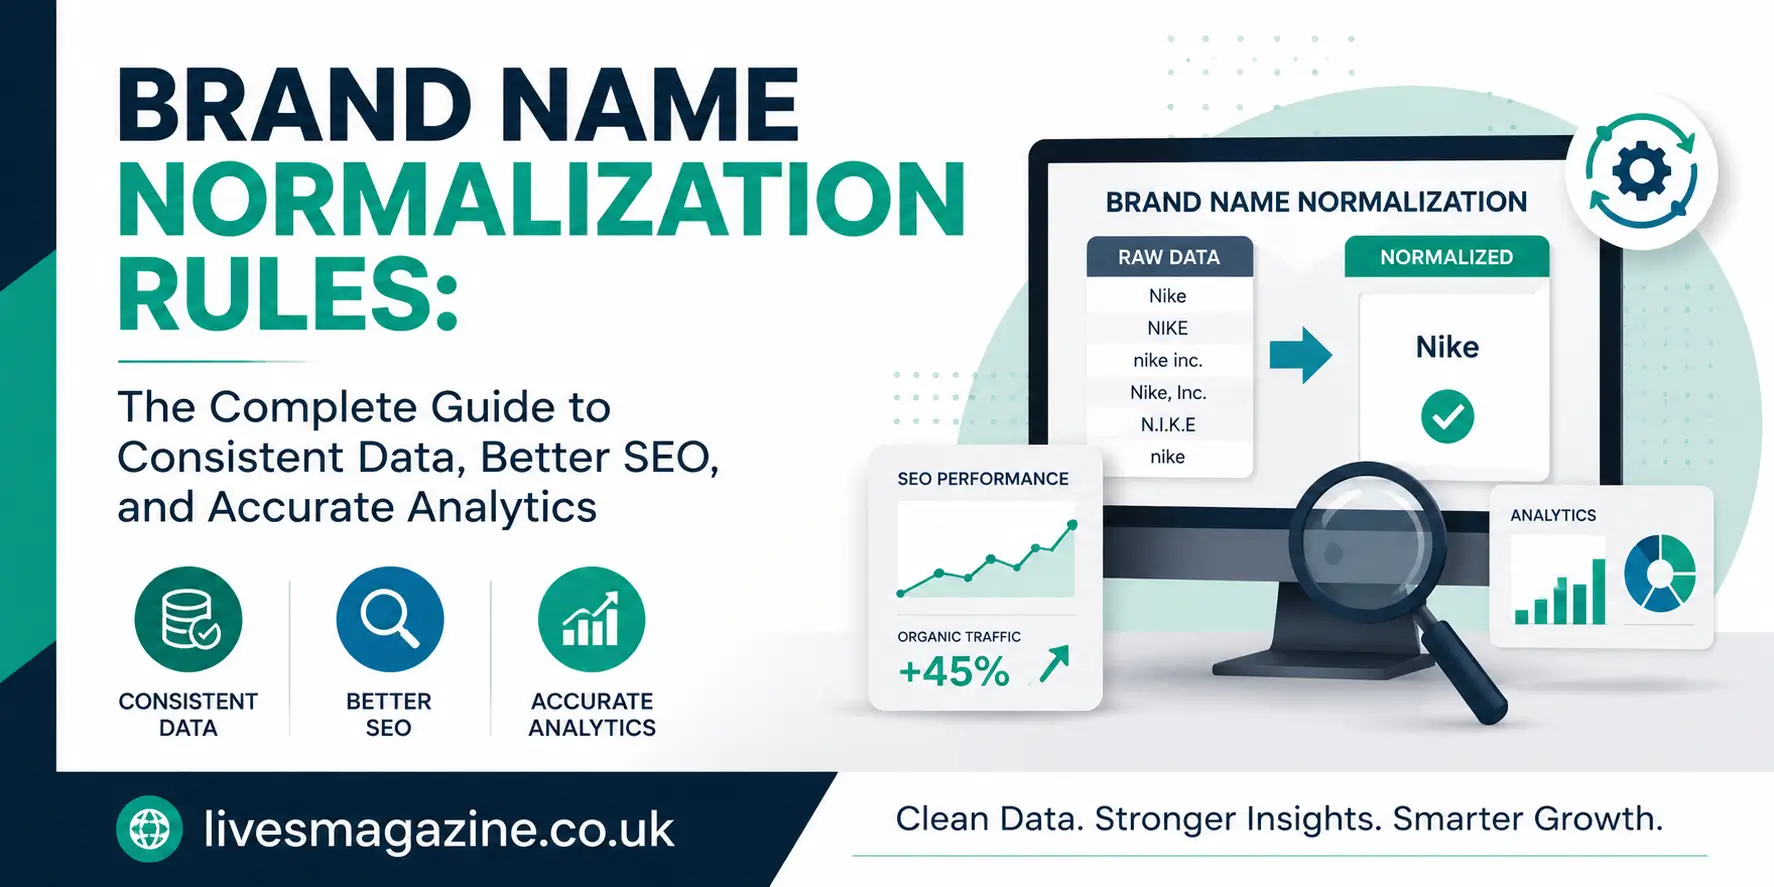
Brand name normalization rules are structured guidelines that standardize variations of a brand’s name across systems, platforms, and datasets. At their core, these rules ensure that multiple versions of a name — whether due to typos, formatting differences, or stylistic choices — resolve to a canonical (single, preferred) form.
For example:
- nova tool drops → Nova Tool Drops
- Nova-Tool-Drops! → Nova Tool Drops
- NOVA TOOL DROPS LLC → Nova Tool Drops (if suffixes are excluded)
Normalization improves clarity, reduces duplication, and enables reliable analysis.
Brand Name Normalization vs. Data Normalization
While data normalization (in databases) focuses on organizing table relationships and reducing redundancy, brand name normalization applies specifically to text data, ensuring consistent naming conventions across disparate sources. Both help data quality, but brand normalization puts emphasis on semantic meaning and identity consistency.
Why Brand Name Normalization Is Critical for Businesses
1. Improves Data Accuracy and Reporting
Unnormalized brand data can lead to multiple fragmented entries for the same entity. This causes inaccuracies in analytics, reporting, and BI dashboards.
Studies show:
- Up to 60% of data anomalies result from poor normalization practices.
- Normalized data improves consistency for more than 75% of organizations that implement it.
When your analytics see Nova Tool Drops, NovaToolDrops, and nova tool drops as different entities, revenue attribution, seasonality trends, and customer behavior modeling are compromised.
2. Builds Brand Consistency and Customer Trust
Consistent naming across ads, product listings, social media, and search results bolsters recognition.
A fragmented brand representation:
- Confuses customers
- Reduces trust
- Splits engagement metrics
While metrics vary by industry, survey data indicates that poor data consistency typically makes insights less reliable — hurting B2C brands especially when customers encounter inconsistent names across platforms.
3. Boosts SEO and Search Visibility
Search engines treat slight variations as separate entities unless properly normalized — which can dilute brand relevance for keywords and reduce organic search visibility.
Brand normalization unifies:
- keyword variations
- structured data markup
- title tags and meta descriptions
… helping search engines associate all mentions with the canonical brand, improving SERP authority.
4. Enhances Marketing and Advertising Performance
Normalized brand names result in:
- better keyword targeting
- higher click-through rates
- accurate ad spend allocation
This is because keyword match quality improves when brand mentions are uniform across targeting sets — particularly in paid campaigns where bid strategies depend on exact matches.
5. Operational and Cost Efficiency
Beyond marketing and SEO:
- Clean data cuts down manual reconciliation
- Reduces storage overhead due to redundancies
- Boosts query performance and integration efficiency
Normalization can reduce storage costs by up to 30% and cut data redundancy by 50–90% according to usage reports.
Common Brand Name Variation Problems
Brand names don’t stay neat. They evolve organically — and that creates data challenges.
Typos and Misspellings
User input. OCR scans. Third-party uploads.
Examples:
- Nova Tool Dops
- Nova Tol Drops
These variations might refer to the same brand but appear as distinct entries in systems unless normalized.
Capitalization Inconsistencies
Differences in capitalization — from ALL CAPS to all lowercase — create multiple representations of the same brand. Strong normalization rules specify a consistent case, like Title Case, unless intentionally stylized otherwise (e.g., “adidas”).
Spacing, Symbols, and Punctuation
Hyphens, underscores, extra spaces, and symbols add noise:
- Nova-Tool-Drops vs Nova Tool Drops
Normalization removes irrelevant separators and unifies format.
Abbreviations and Acronyms
Acronyms like “NTD” should map back to the full brand name to avoid fragmenting data across dashboards.
A synonym dictionary is often used for this.
International and Multilingual Variations
Different markets adapt language and spelling. Localized variations may include:
- “Nova Herramienta Drops” (Spanish)
- “Nova Outil Drops” (French)
Mapping these variations to a core brand name ensures global consistency.
Core Brand Name Normalization Rules (Best Practices)
Here’s a practical rule set that any brand can adopt or adapt.
Rule 1: Standardize Capitalization
Convert all names to a consistent case.
Example:
- nova tool drops → Nova Tool Drops
Exceptions apply when a brand intentionally stylizes its name in all lowercase or a unique pattern.
Rule 2: Handle Spacing and Punctuation
Strip out extra spaces, separators (unless meaningful), and punctuation not part of the brand name.
Example:
- Nova-Tool-Drops! → Nova Tool Drops
Rule 3: Manage Legal Suffixes
Decide whether to include or remove corporate suffixes like Inc., Ltd., or LLC based on your use case.
For core brand data: often removed.
For legal and contracts: often retained.
Rule 4: Abbreviation Mapping
Maintain a synonym dictionary or mapping table:
- “NTD” → “Nova Tool Drops”
- “N.T.D.” → “Nova Tool Drops”
Rule 5: Handle International Variations
Use translation tables to map localized names to the canonical form.
Example:
- Nova Herramienta Drops → Nova Tool Drops
Rule 6: Phonetic Normalization
Phonetic algorithms like Soundex or Metaphone help detect similar sounding names regardless of spelling variation — especially useful for voice search optimization and international naming differences.
Rule 7: Error-Tolerant Matching
Rules should allow for fuzzy matches to catch near-matches and misspellings — improving both search functions and database deduplication processes.
Advanced methods include Jaro-Winkler and Levenshtein Distance-based matching.
Step-by-Step Guide to Implementing Brand Name Normalization
Here’s a practical workflow you can apply immediately.
Step 1: Audit Your Current Brand Name Data
Export your data from all sources — CRM, product catalogs, reviews, analytics logs.
Sort by name and identify variations.
Bold action: Export and sort — this simple action will reveal duplicates instantly.
Step 2: Define Your Normalization Ruleset
Document each rule with examples.
Include:
- capitalization standards
- punctuation handling
- international mapping rules
- abbreviation dictionaries
Involve stakeholders from marketing, legal, and IT for alignment.
Step 3: Choose Tools and Technology
Options range from manual tools like Excel, OpenRefine, or scripting in Python — to fully automated normalization engines.
Common components:
- ETL integration points
- fuzzy matching modules
- validation dashboards
Step 4: Automate Normalization at Scale
Embed normalization into:
- ETL pipelines
- data ingestion scripts
- real-time API checkpoints
Automation prevents variation proliferation.
Step 5: Test and Validate
Use a sample dataset to validate:
- Accuracy (target 95%+ matches)
- False positives (misclassifications)
- False negatives (missed matches)
Iterate rules as needed.
Step 6: Monitor and Maintain
Schedule quarterly reviews. Update rules when:
- you rebrand
- enter a new market
- expand product lines
Governance dashboards help track compliance.
Rule-Based vs Machine-Learning Name Normalization
Traditional Rule-Based Systems
Rule-based approaches use:
- exact patterns
- synonyms
- abbreviation lists
Strengths:
- predictable behavior
- easy to explain
Limitations:
- struggles with unseen variations
- requires extensive manual updates
Machine Learning for Name Matching
Machine-learning approaches use statistical models and pattern recognition to handle fuzzy matches and edge cases that rules alone can’t catch.
Benefits include:
- automatic learning from data
- handling phonetic and semantic variations
- adaptability over time
Fuzzy matching, for example, finds near duplicates even when names differ in spelling or structure — drastically improving data deduplication and search accuracy.
Phonetic Algorithms and NLP
Algorithms like Soundex and Metaphone convert text into phonetic codes to compare similar sounding names. This is especially helpful for voice search and international name variations.
Combining AI with Human Oversight
Machine models excel at pattern detection, but human context ensures cultural variations, branding strategy, and legal naming norms are respected.
The best brand normalization frameworks blend both.
Tools and Software for Brand Name Normalization
Here are effective tools across skill levels:
OpenRefine (Free)
Great for batch cleanup and exploratory normalization.
Spreadsheet Techniques (Excel / Google Sheets)
Useful for small-scale normalization, manual rule application, and quick scripts.
Python Libraries
- FuzzyWuzzy / RapidFuzz for fuzzy matching
- NLTK / spaCy for semantic processing
- Custom scripts for phonetic and distance measures
These help build custom pipelines for name matching.
Enterprise Data Quality Platforms
Commercial platforms offer:
- built-in normalization engines
- real-time integration
- dashboards
- rule governance
Examples include Talend, Informatica, and AI-powered normalization tools.
Brand Name Normalization for SEO and Marketing
Normalized brand names help SEO by:
- ensuring consistent keyword usage
- improving crawlability
- strengthening SERP authority
- enabling schema markup across pages
- linking canonical mentions across platforms
Consistent names also improve paid search relevance and reduce mismatched impressions.
Real-World Examples and Case Studies
Case Study: Normalizing a Growing Brand
A fictional e-commerce brand with 12 unique variations of its name in CRM and product catalogs found that compression into a single canonical variant:
- reduced duplicates from ~30% to ~5%
- improved sales attribution clarity
- increased analytics accuracy
These improvements are consistent with industry findings on normalization impacting data quality positively.
Best Practices for Long-Term Success
Implementing rules is not one-and-done.
Integrate with Systems Early
Normalization should happen at data ingestion, not retroactively.
Train Teams on Naming Standards
Human errors often cause variation. Training reduces these manually introduced issues.
Monitor with Dashboards
Track trends, deviations, and exceptions in real time.
Avoid Over-Normalization
Don’t strip information that’s meaningful (e.g., regional brand variants when intentional).
Challenges in Brand Name Normalization and How to Solve Them
False Positives
Matching different brands too aggressively.
Solution: Set strict thresholds for fuzzy matches and manually verify edge cases.
Rebrands and Mergers
Names change over time.
Solution: Version control with historical mapping tables.
Data Scale
Large datasets challenge performance.
Solution: Efficient algorithms, indexing, and batch processing pipelines.
Pros and Cons of Brand Name Normalization
Advantages
- Improved analytics accuracy
- Consistent SEO signals
- Better CRM hygiene
- Reduced duplicated efforts
Limitations
- Initial setup time
- Complexity in global variations
- Risk of over-normalization
Future of Brand Name Normalization
As voice search, multilingual datasets, and AI applications evolve, brand name normalization will leverage:
- neural NLP models
- real-time automated pipelines
- context-aware entity recognition
- cross-platform integration
AI and human insight will continue to converge in sophisticated normalization frameworks.
Frequently Asked Questions (FAQ)
Q: What’s the main purpose of brand name normalization rules?
A: To create a uniform representation of brand names for accurate analytics and consistent search performance.
Q: How often should normalization rules be updated?
A: Quarterly or whenever branding or data source changes occur.
Q: Can normalization improve SEO rankings?
A: Yes — by consolidating keyword use and strengthening consistency across indexed pages.
Q: What tools are best for beginners?
A: Start with OpenRefine and spreadsheet techniques before moving to automated pipelines.
Conclusion
Mastering brand name normalization rules is essential for any brand that relies on data — from analytics and CRM to SEO and customer engagement. By setting clear rules, leveraging the right tools, and combining rule-based and machine-learning strategies, brands can ensure consistent, reliable, and scalable data across the organization.
Whether you’re dealing with small datasets or enterprise systems, brand name normalization shouldn’t be an afterthought — but a foundational part of your data strategy.
Read More : Xeiropraktis