What Is Sruffer DB? A Beginner-Friendly Explanation
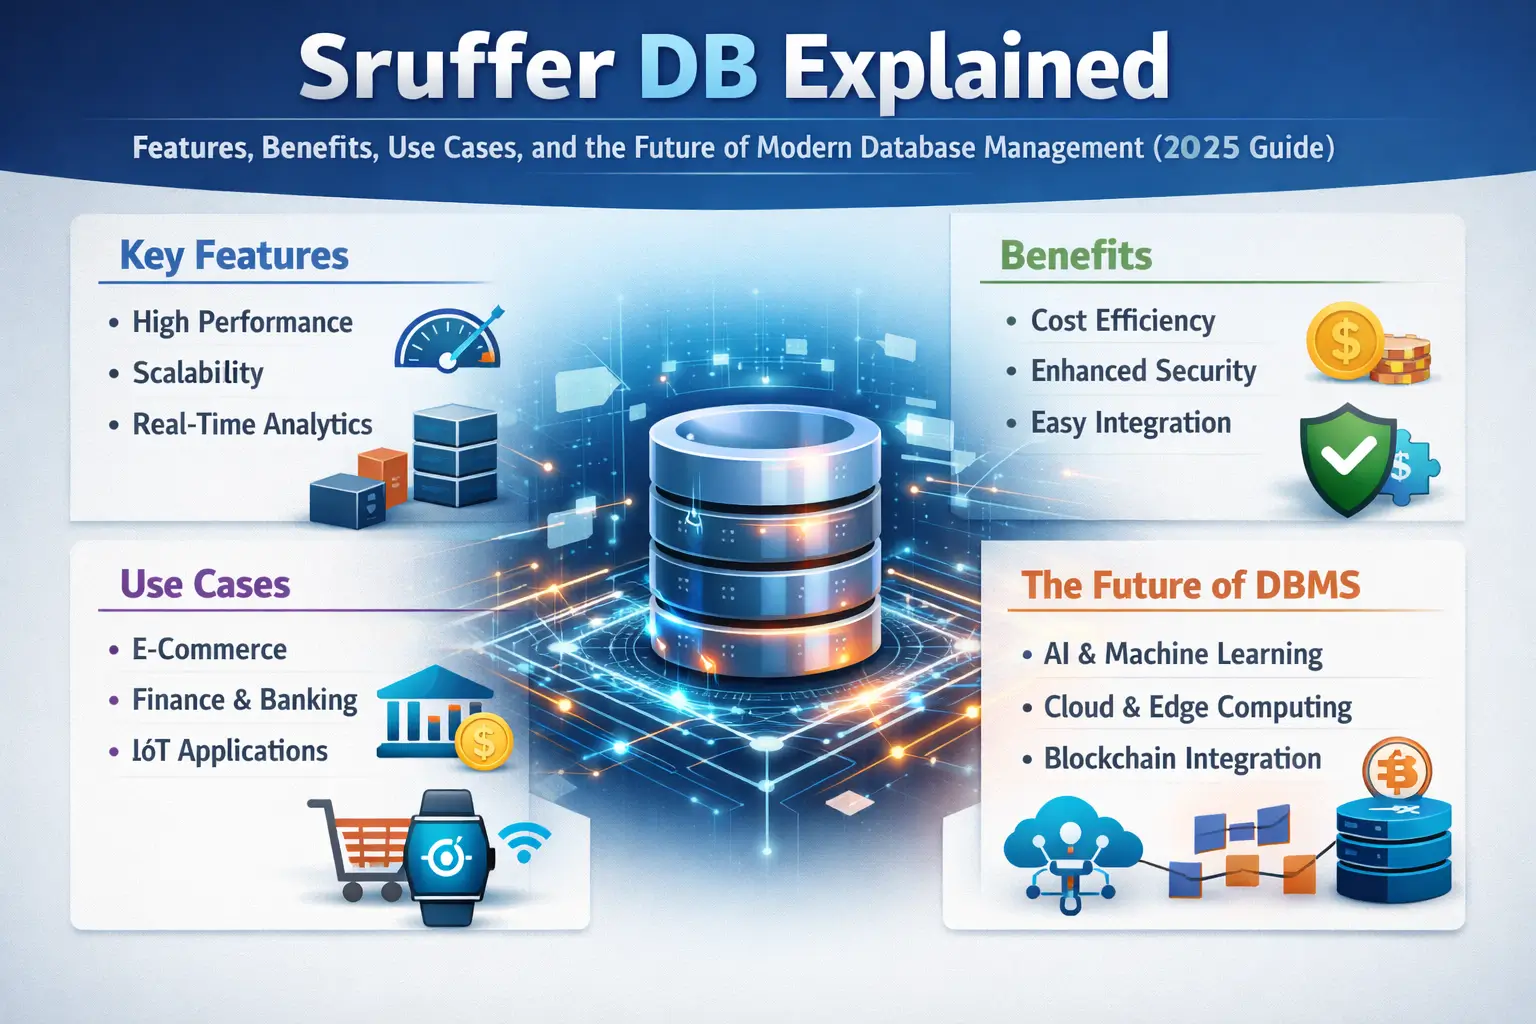
Sruffer DB is described in recent coverage as a modern database management system built to combine storage, processing, and analytics in a single, unified platform. It targets applications that need real-time insights, flexible schemas (or schema-less approaches), and easy cloud deployment. In short, Sruffer DB aims to make it straightforward for product teams to store varied data, query it quickly, and extract near-instant analytics — without the heavy administrative overhead of many traditional relational systems.
At a high level, Sruffer DB is positioned as both:
- A platform (dashboard, short links to management and monitoring, APIs for programmatic control), and
- A philosophy (build for performance + developer ergonomics + telemetry).
This combination is increasingly common among newer DB engines that prioritize developer productivity and operational simplicity.
The History and Evolution of Sruffer DB
Sruffer DB’s public presence has grown recently via tech blogs and niche publications highlighting its architecture and use cases. While detailed corporate histories vary by source, the narrative typically emphasizes that Sruffer DB emerged to address the limitations of strict relational schemas and batch-centric analytics. Contributors from open-source communities and startups helped shape early releases, and subsequent iterations focused on cloud readiness, real-time processing, and security features to meet enterprise needs. These community and product milestones are important because they determine maturity, ecosystem support, and long-term viability.
Understanding Traditional Databases: Strengths and Limitations
Before sizing up Sruffer DB, it helps to recap what legacy systems do well — and where they struggle.
Strengths of traditional relational databases (e.g., many on-prem SQL systems):
- Mature ACID transactions and data integrity guarantees.
- Powerful, standard SQL for complex queries and joins.
- A large ecosystem of tools, DBAs, and enterprise support.
Limitations in modern contexts:
- Rigid schemas make iterative development and unstructured data difficult to manage.
- Scaling horizontally often requires significant re-engineering or complex clustering.
- Batch processing pipelines add latency for analytics; real-time insights are harder and more expensive.
These limits created space for cloud-native, schema-flexible systems and analytics engines that focus on concurrency and low latency. Sruffer DB positions itself squarely in that modern camp. (Traditional vs. modern tradeoffs are important when evaluating migration risk and expected benefits.)
Sruffer DB vs Traditional Databases: Key Differences Explained
If you need a quick comparison, here are the most meaningful distinctions:
Architecture
- Traditional DBs: Often monolithic or scale-up clusters with rigid schemas.
- Sruffer DB: Emphasizes modular, cloud-native components — storage, compute, and analytics tightly integrated yet decoupled enough for elasticity.
Data model flexibility
- Traditional DBs: Best for structured, relational data. Schema changes can be costly.
- Sruffer DB: Built to handle structured and semi/unstructured data, enabling developers to iterate quickly.
Real-time analytics
- Traditional DBs: Usually rely on ETL and batch jobs to feed analytics systems.
- Sruffer DB: Provides near-real-time analytics capabilities as part of the core platform, reducing latency for operational insights.
Cost and operations
- Traditional DBs: Upfront licensing, larger operational teams, and hardware investments.
- Sruffer DB: Typically cloud-based consumption models with automated scaling and lower initial capex, which can be attractive for startups and teams seeking predictable operating costs.
Developer experience
- Traditional DBs: Often require dedicated DBAs and careful change management.
- Sruffer DB: Focuses on a more intuitive UI, APIs, and built-in tooling to reduce friction for developers and product teams.
How Sruffer DB Works: Architecture and Core Components
Understanding how Sruffer DB organizes its layers helps you decide whether it fits your stack.
1. Flexible data model and ingestion
Sruffer DB accepts varied inputs — structured records, JSON documents, event streams — and lets teams index and query them without heavy pre-defined schemas.
2. Storage layer
It uses distributed cloud storage patterns (object + tiered storage) so hot and cold data can be managed efficiently. That lowers long-term storage cost while keeping frequently accessed data fast.
3. Compute & query engine
A horizontally scalable compute layer executes queries, supports concurrent read/write workloads, and powers real-time analytics. The engine is optimized for low latency and high throughput for both OLTP-style workloads and analytic queries.
4. API and developer tools
Sruffer DB exposes REST/GraphQL or native client libraries so developers can integrate the DB directly into apps. Management dashboards surface metrics, query plans, and operational alerts.
5. Integrations
Connectors for common data pipelines (streaming, change data capture, ETL) make Sruffer DB usable inside existing ecosystems without ripping and replacing everything.
(These components create a platform that reduces the need for separate analytics clusters or complex ETL jobs for many use cases.)
Key Features of Sruffer DB That Set It Apart
Both reference writeups highlight a consistent set of capabilities. The most important are:
Real-time analytics
Enable instant dashboards and operational triggers (inventory alerts, fraud detection). This contrasts with batch analytics flows common in many legacy setups.
High concurrency and low latency
Designed to handle many simultaneous users and queries without significant slowdown — essential for SaaS platforms and high-traffic apps.
Scalability and elasticity
Sruffer DB scales up or down in the cloud so capacity matches demand, which reduces wasted spend and simplifies seasonal or campaign spikes.
Developer-friendly UX
Dashboards and APIs that reduce complexity for non-DBA teams — speeding time-to-market for features and analytics.
Security and compliance features
Built-in encryption, access controls and enterprise features that support regulated industries (healthcare, finance) — a necessary component for broader adoption.
Benefits of Using Sruffer DB for Modern Applications
If you’re evaluating Sruffer DB versus maintaining a traditional stack, here’s what you gain:
- Faster product iterations: Less time fixing schema migrations or waiting on complex data pipelines.
- Operational simplicity: Cloud automation reduces DBA overhead.
- Lower initial capex: Cloud consumption models mean you generally pay as you grow.
- Near-real-time insight: Improves operational responsiveness (inventory, fraud, customer experience).
- Better developer experience: APIs and UIs free up engineering time for feature work.
These benefits can translate into measurable business outcomes: quicker launches, fewer incidents, and more accurate analytics-driven decisions.
Real-World Use Cases of Sruffer DB Across Industries
The literature highlights several industry patterns where Sruffer DB excels:
E-commerce & inventory management
Real-time stock updates, fraud detection, and campaign analytics are central. A Sruffer DB deployment can centralize product, customer, and telemetry data for instant, actionable insights.
Healthcare & telemedicine
Fast access to patient records, real-time monitoring data, and secure handling of sensitive records make flexible, secure databases valuable in clinical workflows. Sruffer DB’s encryption and compliance tooling are critical here.
Fintech & payments
High concurrency and low latency are vital for transaction processing and reconciliation; Sruffer DB’s architecture helps reduce transaction friction while preserving auditability.
SaaS & startups
Startups benefit from pay-as-you-grow pricing, fewer operational tasks, and the ability to iterate on product data models.
AI/analytics startups
Because Sruffer DB includes rapid analytics, teams can prototype and iterate on models using live data without a heavy analytics stack.
(These cross-industry examples show where Sruffer DB’s mix of flexibility, security, and real-time capability is most valuable.)
Cost Comparison: Is Sruffer DB More Cost-Effective Than Traditional Databases?
Short answer: It depends on scale, workload patterns, and organizational capabilities — but cloud-native, consumption-based models typically reduce upfront expenses and operational overhead.
Where you save
- No massive hardware spend — the cloud model removes large capex.
- Lower staffing costs — fewer specialized DBAs required for routine tasks.
- Elasticity — avoids overprovisioning for peak loads, which can significantly reduce waste.
Where costs remain
- Data egress & storage tiers — cloud costs can accumulate on high volumes or cross-region traffic.
- High sustained throughput — very large, consistent workloads might still be cheaper to run on well-tuned, self-managed infra depending on scale.
Market context: the global cloud database and DBaaS market is growing rapidly — projected at tens of billions of dollars in 2025 and expected to expand at double-digit CAGR through the decade — which reflects both demand and the economics of cloud database consumption. Analysts estimate the cloud DB/DBaaS market is in the low-to-mid tens of billions in 2025 with strong multi-year growth. (See cited market reports for exact forecasts.)
Practical advice: Run a short-term TCO model comparing your current cost profile (licensing + hardware + DBA salaries + downtime risk) versus a Sruffer DB pricing estimate (ingestion, storage, compute). For many fast-growing startups and variable-load apps, the cloud model is financially attractive.
User Experience, Adoption, and Community Feedback
Public writeups and reviews emphasize a friendly UI, helpful onboarding, and responsive support. That user experience is a strong differentiator because it shortens the learning curve for dev teams and product managers. Positive customer testimonials highlight faster query response times and simplified operations; these social proof signals are often critical for adoption in mid-market and enterprise buyers.
Adoption is tied to community and documentation: platforms with active forums, thorough guides, and open samples accelerate adoption across teams. If you’re adopting Sruffer DB, budget time for developer education and initial integration.
Security, Data Protection, and Reliability in Sruffer DB
Security and compliance are non-negotiable, especially in regulated industries.
Typical Sruffer DB security features reported:
- End-to-end encryption at rest and in transit.
- Role-based access control and audit logs.
- Backup & recovery features plus data retention controls.
These capabilities are necessary to pass internal audits and meet regulatory needs like HIPAA or PCI DSS when relevant. When evaluating Sruffer DB, request documentation about encryption standards, key management, and SOC/ISO certifications.
Challenges and Limitations of Sruffer DB
No technology is perfect. The most commonly flagged challenges are:
1. Migration complexity
Moving large legacy databases to a new model requires planning. Schema mapping, data cleansing, and ensuring transactional integrity are non-trivial. Expect investment in migration tooling and testing.
2. Ecosystem maturity
As a newer entrant, Sruffer DB may have a smaller ecosystem of third-party tools, connectors, or consultants compared with major relational systems.
3. Performance tuning at scale
While Sruffer DB targets high concurrency, extreme scale customers (think global ad platforms or real-time trading systems) will still need careful architecture and likely hybrid models.
4. Learning curve and organizational change
Teams must adjust to new concepts (e.g., different query languages, new monitoring dashboards), so plan training and pilot projects.
These are typical early-adoption tradeoffs. A thorough pilot and staged migration reduce risk.
The Future of Sruffer DB in the Tech Industry
The broader market context is favorable for cloud-native databases: cloud spending and DBaaS adoption are accelerating as organizations invest in AI, real-time analytics, and low-latency services. Analysts project robust growth in the cloud DB and DBaaS markets through the decade, driven by digital transformation and AI workloads. For Sruffer DB this means opportunity — but also competition from focused offerings like specialized real-time analytics engines and established cloud providers.
Key near-term trends to watch:
- AI + DB integration: Databases that support feature stores and fast model serving will gain traction.
- Edge and distributed architectures: Low-latency global applications will demand geo-distributed data layers.
- Consumption pricing & observability: Customers will prefer transparent pricing plus rich telemetry.
Sruffer DB’s success will depend on execution: ecosystem growth, third-party integrations, enterprise security posture, and evidence of scale in production.
Cost & ROI Case Example (Hypothetical)
To illustrate ROI, consider a mid-sized e-commerce company migrating seasonal campaign analytics from a batch pipeline to Sruffer DB:
- Before (batch pipeline): ETL latency 6+ hours, separate analytics cluster billing $X/month, DBA time for maintenance 0.5 FTE.
- After (Sruffer DB): Real-time analytics, reduced ETL costs, lower operational overhead, improved CTR from timely promotional tweaks.
Potential measurable outcomes:
- Faster campaign optimizations → +5–10% uplift in conversion.
- Lower operational spends on maintenance → reallocate 0.25–0.5 FTE.
- Reduced data pipeline infra → 10–30% lower monthly infra cost (varies).
Run your own modeling with conservative estimates, but many adopters report meaningful operational and revenue uplifts when real-time decisioning improves conversion and reduces stockouts. (Note: your mileage will vary — run a proof of concept.)
Frequently Asked Questions About Sruffer DB
Is Sruffer DB good for large enterprises?
Yes — with caveats. Enterprises will want evidence of scale, compliance certifications, and migration playbooks. Sruffer DB’s modern features suit enterprise needs, but do pilot projects and demand security attestations.
How does Sruffer DB differ from SQL databases?
Sruffer DB emphasizes schema flexibility, real-time analytics, and cloud elasticity versus traditional SQL’s strong ACID guarantees and rigid schemas. The two models are often complementary rather than strictly competitive, depending on workload.
Can I migrate existing applications to Sruffer DB?
Yes, but plan carefully. Migrations need mapping, testing, and validation. Start with non-critical workloads or read-replica patterns to validate performance and correctness.
Will Sruffer DB replace traditional databases?
Unlikely to completely replace them. Relational databases remain crucial for many transactional systems. Sruffer DB is better viewed as a modern complement for workloads that benefit from schema flexibility, analytics, and real-time behavior.
Practical Adoption Roadmap (6 Steps)
- Pilot use case: Choose a narrow, high-value workload (inventory, analytics, feature store).
- Proof of concept: Ingest sample data, run typical queries, and monitor latency and cost.
- Integration testing: Hook Sruffer DB into your auth, logging, and backup systems.
- Migration plan: Map schemas, establish change windows, and plan rollback paths.
- Optimize: Tune indices/partitions, set retention policies, and set up alerts.
- Scale & expand: Move additional services after performance and security validation.
Final Thoughts: Is Sruffer DB Worth Using in 2025?
If your organization values real-time insights, developer productivity, and cloud elasticity, Sruffer DB is worth evaluating. It is especially compelling for teams that juggle varied data shapes and need faster decision loops (marketing, e-commerce, SaaS telemetry, fintech prototypes). However, adoption should be measured: run pilots, validate security and compliance, and model total cost of ownership against your workload characteristics.
The broader industry is investing heavily in cloud databases — analysts estimate the cloud DB/DBaaS market is growing rapidly and will continue to command a larger share of enterprise infrastructure budgets as AI and real-time analytics become must-have capabilities. If Sruffer DB can prove operational maturity, robust security, and ecosystem integrations, it stands to be a notable player in this expanding market.
Read Also:- URLwo Explained